Building Models with Saturn Cloud and Deploying via Nebius Token Factory
Train models on H100/H200 GPUs with Saturn Cloud on Nebius infrastructure, then deploy to production via Token Factory's optimized …
A practical comparison of cloud platforms for LLM training, covering H100 pricing, multi-node support, interconnects, and operational overhead.
Read article →
Train models on H100/H200 GPUs with Saturn Cloud on Nebius infrastructure, then deploy to production via Token Factory's optimized …
How bare metal GPU providers can deliver a complete AI development platform using Mirantis k0rdent for infrastructure management and …
Deploy NVIDIA NIM containers for LLM inference on Saturn Cloud. Get optimized inference endpoints without managing Kubernetes or GPU …
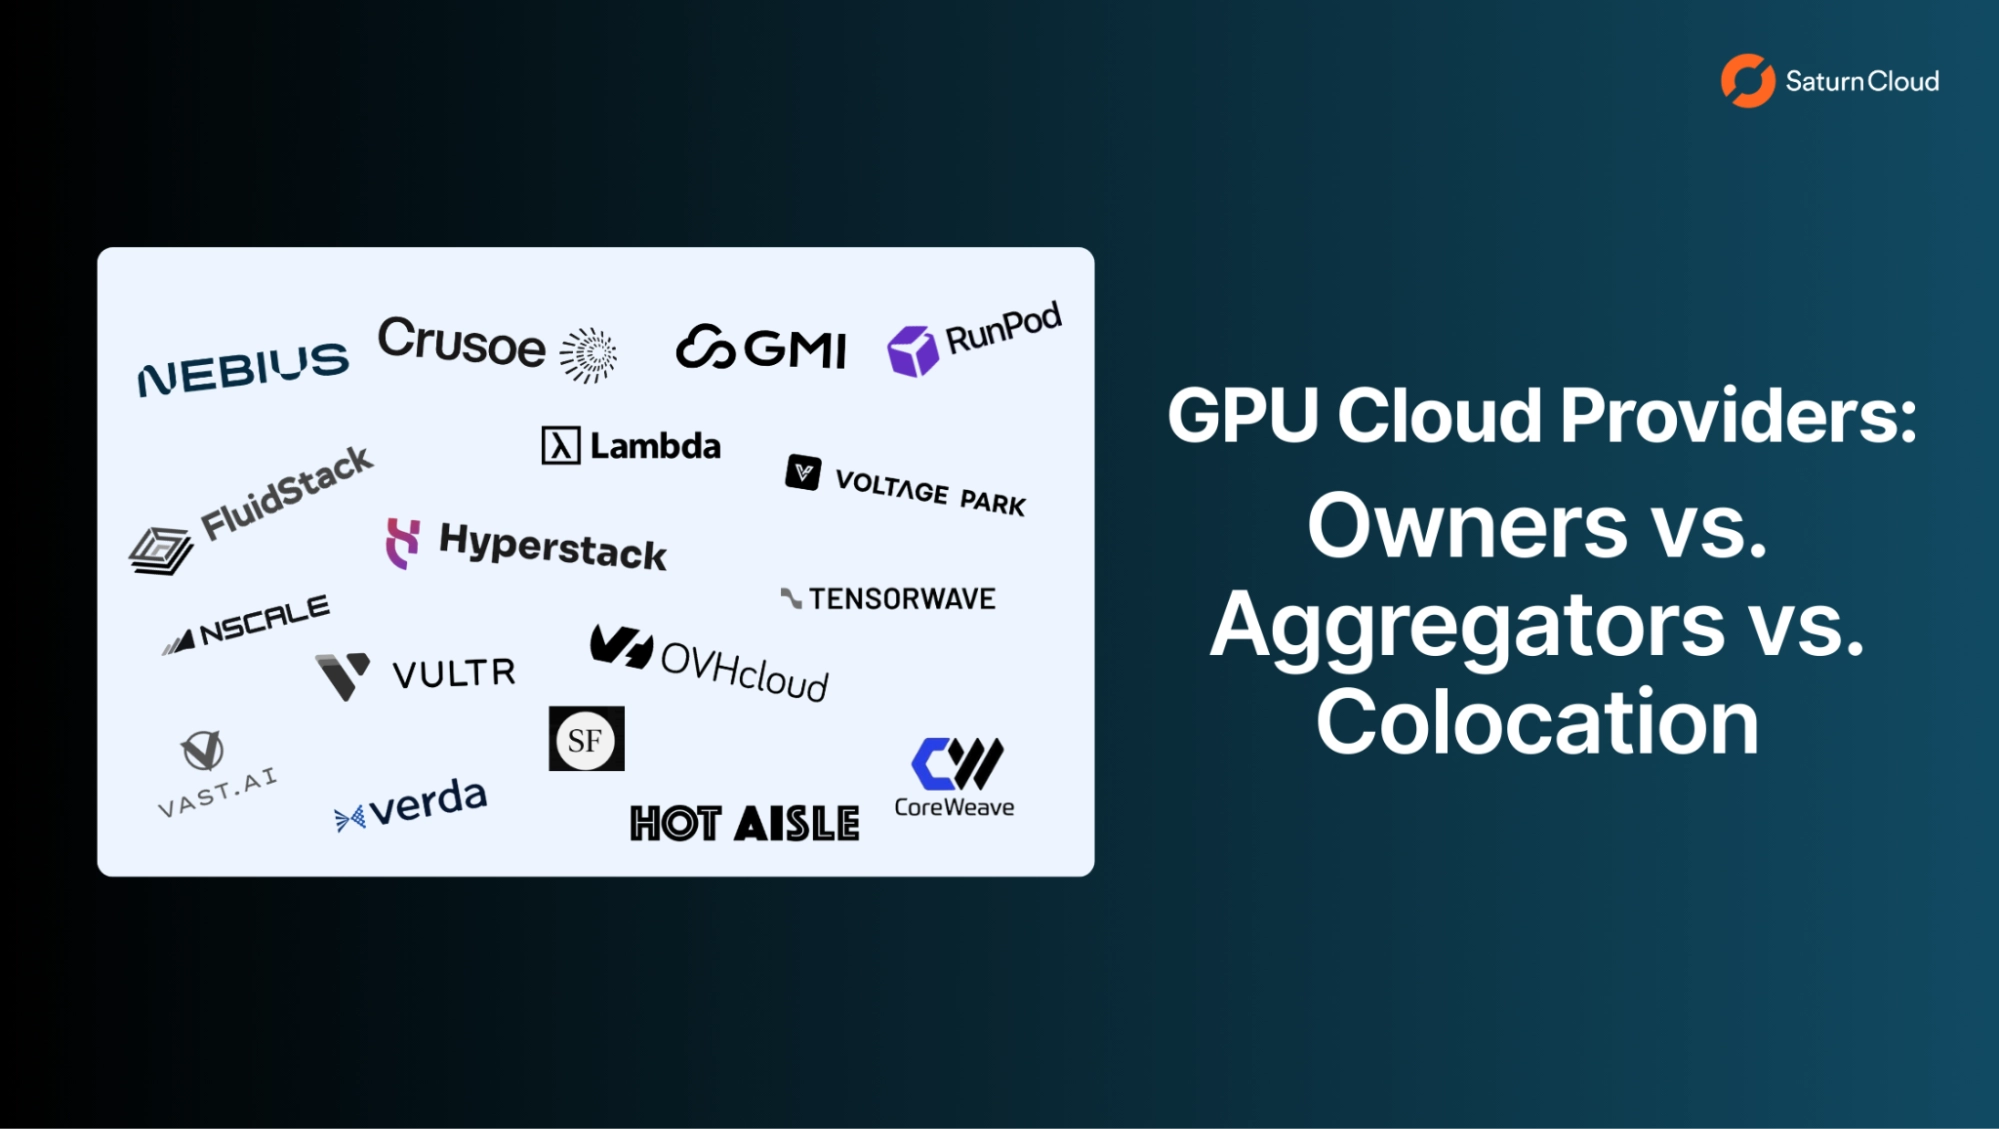
GPU cloud providers fall into three categories: owners who control their data centers and hardware, hardware owners who use colocation, …
InfiniBand matters for distributed training across 16+ GPUs. For single-node workloads, standard networking is fine. This guide …
Why HPC teams want SLURM semantics even when they have Kubernetes, and how to get both on Nebius AI Cloud
How to run NCCL all_reduce benchmarks to verify your GPU cluster's interconnect performance before running production training.
Provisioning multi-GPU clusters with InfiniBand and NVLink using the Crusoe Terraform provider for distributed training workloads.
How to deploy Saturn Cloud on Crusoe for teams that need H100, H200, and GB200 GPUs without hyperscaler quota constraints.